Supported Flat Data Domains
Overview
While many organizations consume data in the FHIR® format, implementing and maintaining FHIR® integrations can require significant resources. To address varying technical capabilities and priorities, Particle Health offers an alternative flattened data format designed for faster integration and ingestion into downstream systems.
The flat structure simplifies data processing and persistence compared to the hierarchical complexity of FHIR®. Delivered in formatted JSON, the flat output consists of datasets specified in the parameters of the GET /flat/{id}/collect-data[parameters]API request.
Each dataset corresponds to a specific clinical domain (e.g., Labs, Encounters) and is structured as a list of dataset entries. This format allows for more efficient parsing, storage, and utilization of the data within customer systems.
Supported Flat Domains
| Dataset | Query parameter | Response key |
|---|---|---|
| Allergies | ALLERGIES | allergies |
| Coverages | COVERAGES | coverages |
| Document References | DOCUMENT_REFERENCES | documentReferences |
| Encounters | ENCOUNTERS | encounters |
| Family Member Histories | FAMILY_MEMBER_HISTORIES | familyMemberHistories |
| Immunizations | IMMUNIZATIONS | immunizations |
| Labs | LABS | labs |
| Locations | LOCATIONS | locations |
| Medication Fills | MED_FILLS | medicationFills |
| Medications | MEDICATIONS | medications |
| Organizations | ORGANIZATIONS | organizations |
| Patients | PATIENTS | patients |
| Practitioners | PRACTITIONERS | practitioners |
| Problems | PROBLEMS | problems |
| Procedures | PROCEDURES | procedures |
| Record Sources | RECORD_SOURCES | recordSources |
| Social Histories | SOCIAL_HISTORIES | socialHistories |
| Sources | SOURCES | sources |
| Transitions | TRANSITIONS | transitions |
| Vital Signs | VITAL_SIGNS | vitalSigns |
Dataset query parameters are not case-sensitive.
The Medication Fills dataset requires a Surescripts license.
How to link the data models
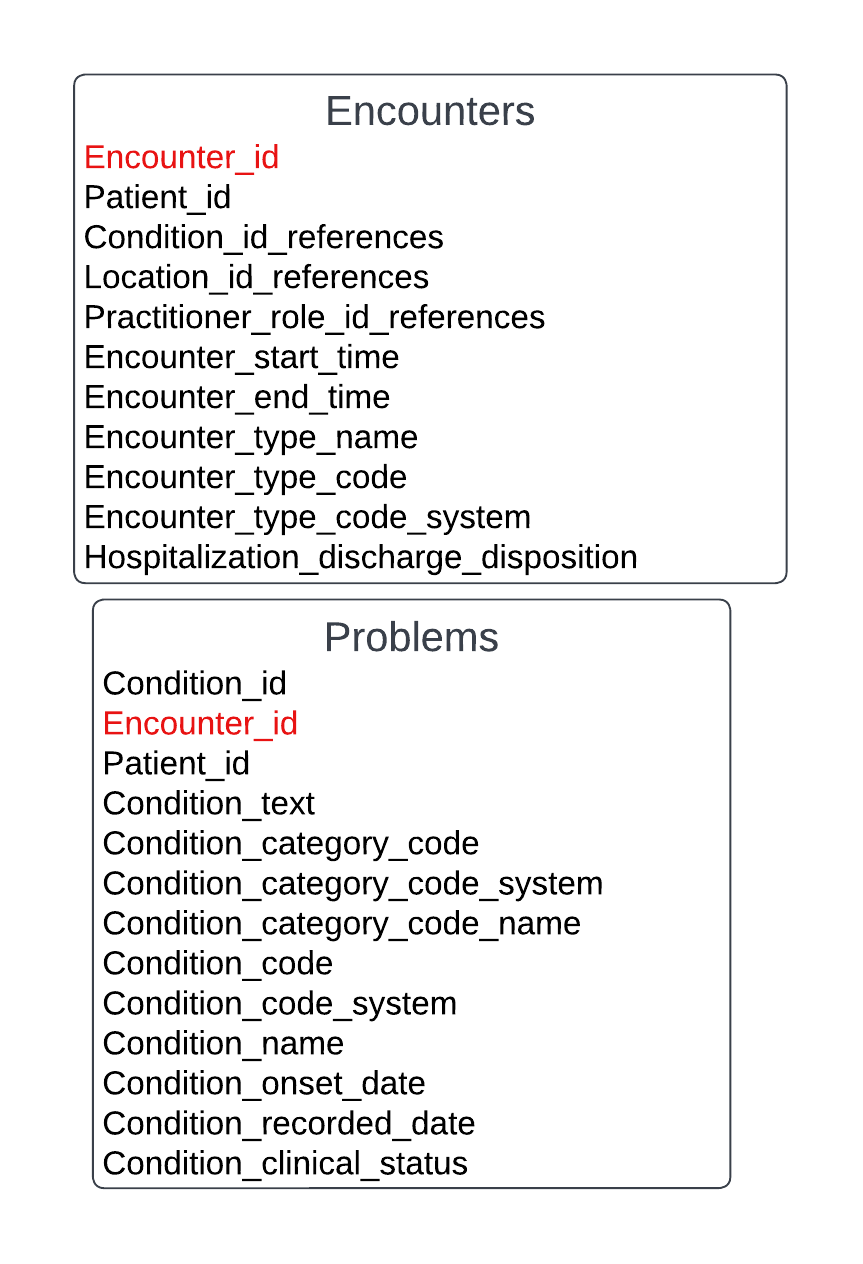
To gain additional clinical context with the Flat datasets, each dataset contains a primary key(s) and/or foreign key(s) that allow you to link the various tables together. For example, if you were interested in which encounter a diagnosis was made, you can link the Problem entry to an Encounter entry. To do this, link the encounter_id on the Problem entry to the encounter_id on the Encounter entry.
Example
Below is an example illustrating the structure of the Labs and Encounters datasets in the Flat output format. Each dataset is returned under its response key (see the table above), and each entry's fields use snake_case names (e.g., encounter_id).
{
    "labs": [
        {
            "field_1": "value_1",
            "field_2": "value_2",
            "field_n": "value_n"
        },
        {
            "field_1": "value_1",
            "field_2": "value_2",
            "field_n": "value_n"
        }
    ],
    "encounters": [
        {
            "field_1": "value_1",
            "field_2": "value_2",
            "field_n": "value_n"
        },
        {
            "field_1": "value_1",
            "field_2": "value_2",
            "field_n": "value_n"
        }
    ]
}
Updated 10 days ago